VKS makes it easy to give every team its own Kubernetes cluster: VCF Automation hands them out, Cluster API keeps them reconciled, and the Supervisor runs them on the vSphere you already operate. As the number of clusters grows, the natural next step is to see the whole fleet at once: which clusters need attention, what is about to run out, and what a change will do before you make it. That is what I built vks-fleet for.
vks-fleet is an open-source plugin for Headlamp that brings the Supervisor, vCenter, each cluster’s API and its Prometheus together in one view, for operators, read-only admins and tenants alike.
A personal project. vks-fleet is something I built in my own time. It is not a Broadcom or VMware product, not endorsed or supported by either, and it uses only public APIs. It is Apache 2.0, and the code is on GitHub.
The fleet dashboard, in demo mode: a score, what needs you now, eight blocks that each open their page, and every cluster as a tile.
Day-2 questions at fleet scale
VKS gives you a lot out of the box. Cluster API reconciles your clusters, the Supervisor carries the control plane, and VCF Automation hands out self-service. Once there are many clusters, operators start asking fleet-level questions like these:
Which of my clusters needs attention right now, and which of those is actually urgent?
A node has been “deleting” for a day. Is that a PodDisruptionBudget, a volume that won’t detach, or the ESXi host underneath?
Which disk, volume or certificate runs out in the next 30 days?
If I upgrade this cluster, or scale this pool down, what breaks, what moves, and does the namespace have room while it rolls?
What is open security-wise across every cluster, not just the one I happen to be logged into?
Every answer is already there, spread across a kubectl session per cluster, vCenter, the Supervisor’s own namespaces and each cluster’s Prometheus. vks-fleet brings them onto one screen, so the same questions take seconds whether you run three clusters or thirty.
Why a Headlamp plugin
I started out thinking about forking a Kubernetes UI and went the other way. Headlamp is an open-source Kubernetes web UI with a proper plugin system: it already handles sign-in, kubeconfig contexts, per-cluster views, logs, shells and YAML. A plugin can add pages, read any cluster Headlamp is signed in to, and hand off to Headlamp’s own views when you want the raw objects. That meant I could spend the effort on the fleet layer and let Headlamp do the rest.
It also keeps the footprint small. The plugin runs in your browser with Headlamp’s sign-ins. There is no server of its own, no database, no agent in your clusters and no telemetry.
How it is built to work
The plugin follows the way an operator actually works through a problem:
ObserveOne dashboard for the fleet, a score with its trend, and what needs you now.
DetectRanked issues, each with its cause, and the steps that clear the most of them.
ExplainA cluster’s timeline beside a walk down the layers under a node.
PredictWhat runs out in 30 days, and what a change will do before you start it.
ActControlled changes, each with its checks and a server-side dry run.
Watch it in a minute: a one-minute walk through demo mode (the dashboard, investigating a node, a fix with its dry run, pre-flight, Supervisor health, security and what to do first) is at the top of the project’s README.
Observe: one screen for the fleet
The fleet page opens on a dashboard. At the top is a fleet score (the average of each cluster’s best-practice checks) with a 30-day trend, and a short Needs you now list that puts time-bound problems first: a node disk that fills in two days outranks a warning that has been there for a month.
Below it are eight blocks: clusters, Supervisor, capacity, the next 30 days, lifecycle, security, governance and network. Each is one number with one line of context, and each opens the page that owns the detail. Under them, every cluster is a tile on a wall, coloured by its worst open problem and grouped by org.
Detect: issues with a cause, not just a list of findings
The plugin folds raw signals into issues that say what is wrong, why, and what to do. A stuck node, a drain blocked by a PodDisruptionBudget, a crash-looping pod, a certificate close to expiry, quota and memory overcommit, controllers that stopped reconciling, Supervisor services all running on one host, packages that fail to reconcile, backups that stopped: each becomes one line with its fix or the decision it needs.
On top of that sits Do these first: the recommended steps that clear the most issues, ranked by effect, each opening where it is done. A Simulate view shows the fleet as it would look with the fixes applied, so you can see the payoff before spending the change window.
Issues: the steps to do first, then every open issue with its fix or the decision it needs.
Explain: from a pod down to the ESXi host
This is the part I use most. Investigate puts one cluster’s timeline (changes, alerts, events and anomalies) beside a walk down the layers under a node: pod, node, Machine, VM, ESXi host, namespace and Supervisor. It names the deepest layer in trouble, so you know whether you are looking at a Kubernetes problem, a VM problem or a host problem. When two troubled nodes share a host, it says so. It also drafts the post-mortem from the same timeline.
Investigate: what happened, beside every layer under the node. Here the deepest layer in trouble is the Machine, stuck deleting.
Predict: the next 30 days, and pre-flight
Forecasts from each cluster’s Prometheus (node disks, memory, volumes), the Supervisor’s control-plane disk from vCenter, and certificate expiries all land on one 30-day timeline.
Pre-flight answers what will this change do? before an upgrade, a node pool scale or a VM class change. It works out which nodes are replaced, which pods move, which single-replica workloads take a brief outage, which disruption budgets or pinned pods would block it, whether the namespace has room for the extra nodes while it rolls, and whether the Supervisor itself is healthy enough to start. Then it gives a verdict: go ahead, go ahead with care, or stop.
Pre-flight for scaling a pool down by one. The verdict is Stop: a node in the pool is already stuck deleting.
For upgrades across many clusters there is an upgrade planner that arranges clusters in waves (a small canary first, then the rest) with the same checks for each cluster.
Act: controlled changes
Upgrades, node pool scaling, node replacement, drain timeouts, package updates, VM power operations and new clusters can all be started from the plugin. Every change shows its checks first and runs a server-side dry run (?dryRun=All), so anything the API or the VKS admission webhooks would refuse is caught before anything changes. Destructive actions ask you to type the cluster’s name.
For shared installations there is a read by default, elevate to change mode: viewing uses a read-only sign-in, and a change needs a time-limited elevation with a reason, recorded on the object it changed.
Supervisor health
Clusters are only as healthy as the Supervisor running them. A Supervisor page shows the control plane, the ESXi hosts and what runs on each, the leader-election leases of the controllers that manage your clusters (a lease that stops renewing means a controller is stuck, even when its pod says Running), Supervisor services, and the reconcile backlog. Click a host and it shows what that host failing would take down. With an optional, read-only collector it also reads vCenter: configuration status, alarms, utilisation and the control-plane VM’s disks.
Supervisor health: the hosts, what runs on each, and what vCenter reports.
Security: what is open, across every cluster
The Security overview shows what is open across every cluster you are signed in to: privileged namespaces, privileged and host-level pods, cluster-admin grants, and image vulnerabilities from Trivy Operator, counted once per image and split into your images and the ones VKS ships. Policy results from Kyverno or any engine that writes PolicyReports appear beside them. A cluster without a scanner reads not measured, never zero.
Security overview: what is open across the fleet, then one row per cluster.
Principles behind it
Principle
What it means in practice
Public APIs only
Cluster API, VM Operator, NSX VPC, Carvel, Prometheus, and vCenter through a small read-only collector. No private interfaces.
Nothing installed in your clusters
Everything is read through the APIs that are already there. Trivy, Kyverno and Prometheus are used when present, never required.
Your RBAC decides what you see
Operators see every org, read-only admins see everything and change nothing, tenants see only their own org. It follows the account Headlamp signs in with, not a mode in the UI.
Honest numbers
Data that can’t be read is “not measured”, not zero or passing. Every figure says where it came from.
Dry run before every change
Checks, then a server-side dry run, then confirmation. If a multi-step change fails partway, it says which steps took effect.
Try it without a lab
The fastest way to see it is demo mode: a fictional fleet with realistic problems built in, where nothing is ever changed. Install the plugin, open VKS fleet and choose Try the demo. You can scale the demo fleet up to 50 clusters to see how the pages behave at size.
Headlamp desktop app or Docker: download vks-fleet.tar.gz from the latest release, extract it into Headlamp’s plugins folder, restart Headlamp and open VKS fleet.
In a cluster, with Helm: the chart installs Headlamp, the plugin, and a job that keeps the Supervisor sign-in fresh. The quick start has the full commands, including trusting vCenter’s CA so certificates are verified; the core of it is:
Then connect your Supervisor under Settings → Plugins → vks-fleet. It is also listed on Artifact Hub as a Headlamp plugin.
Where it stands, honestly
It is developed and tested against VCF 9.1 with VKS 3.7 on Headlamp 0.45, on a real lab with one Supervisor, two VKS clusters and VCF Automation tenants. Every read and view has been checked there, as have the vCenter collector and changes through the VKS admission webhooks: scaling node pools up and down, pausing and resuming clusters, and a clean Helm install under restricted Pod Security with verified TLS.
What is not yet confirmed on a live system: deletes through the plugin, drain timeouts on machines that are already deleting, and some links into Headlamp’s own pages. The checks also run from the browser, which suits tens of clusters; demo mode exercises the pages at 50, but a real fleet has so far been tested at two. The README’s validation status keeps the current list.
If you run VKS, I would genuinely like to hear how it behaves on your fleet, especially with more clusters, more than one Supervisor, or tenants coming in through VCF Automation.
vks-fleet is a personal open-source project under the Apache 2.0 licence. It is not affiliated with, endorsed by, or supported by Broadcom or VMware. Product names are used only to describe what it works with.
A VKS cluster is built in layers, and different teams own different layers. A pod sits below anything kubectl will show you, and above anything vCenter will show you. That is true of Kubernetes on any virtual infrastructure, but it does mean very few people ever see the whole picture at once. This post walks the entire path, one layer at a time: what happens inside the node, what happens inside the virtual switch in the guest, and what happens when someone exposes a pod with a LoadBalancer Service and a user connects to it from outside.
I have drawn this on a whiteboard often enough that it seemed worth writing down properly. If you have ever had to answer one of these, this post is for you:
Where should a pod-level firewall rule actually be written?
Why does my application log every request as coming from the same address?
Is AntreaProxy a process? What happens to my traffic if it restarts?
How does a LoadBalancer Service actually get its address?
Where does a packet really go when one pod talks to another?
Every one of those is the same question in a different costume: where does the packet go, and who rewrites it on the way?
One note before we start. Networking people say SNAT when they mean “rewrite the source address” and DNAT when they mean “rewrite the destination address.” Both appear a lot below, and almost everything confusing in this post comes down to one of them happening somewhere you did not expect.
The whole path, bottom up
Read this from the bottom up, in the direction an arriving packet travels. Everything here is the NSX overlay design. The other switching model is a post of its own.
Count the layers as you go. That number explains most “why is this so hard to troubleshoot” conversations on this platform.
The VKS data path on NSX overlay networking. Three hypervisor hops, and four inside the guest where vCenter can no longer see them.
What the diagram makes obvious is that the path crosses three ownership boundaries: the guest operating system and its CNI, the ESXi virtual switch, and the physical network. Each one is well instrumented on its own. None of them shows you the other two. That is the real reason a networking question here is hard to answer from a single console, and it is why this post walks the whole path instead of any one layer of it.
Inside the node: one switch, everything plugged into it
Now zoom in on the guest. The correction I make most often in a room is this: br-intis the OVS bridge. There is no OVS on one side and a bridge on the other. There is one bridge, it is called br-int, and everything plugs into it.
One node, drawn honestly. Each pod’s veth peer is a port on br-int. antrea-gw0 is the pod network gateway; antrea-tun0 carries pod traffic between nodes.
Every pod is connected by a veth pair, which is best thought of as a short virtual cable. One end is the pod’s eth0. The other end is a port on br-int. Two other ports matter: antrea-gw0 is the pod network’s gateway on this node, and antrea-tun0 is the tunnel port used only when a pod talks to a pod on a different node.
Three things live on that bridge, and it is worth being precise about which does what, because the names mislead:
Component
What it actually is
ovs-vswitchd
The user-space daemon that holds the flow tables. The kernel module underneath is what actually moves packets.
antrea-agent
Control plane only. It writes the rules. It never touches a packet. If it stops, existing traffic keeps flowing.
AntreaProxy
Not a process at all. It is a set of rules in the bridge: one table picks a backend pod, the next rewrites the destination to that pod’s address. This is what replaces kube-proxy.
The correction that lands hardest. There is no proxy process in the data path. When people say “Antrea does proxying on the bridge,” what actually happens is that a packet matches a rule and has its destination rewritten, in the kernel, with nothing in user space involved. That is why AntreaProxy costs almost nothing, and why restarting antrea-agent does not drop traffic.
Inside br-int: the tables a packet walks
This is the level almost nobody goes to, and it is the level where the rest of the post stops being mysterious. A packet enters at a port, walks through a series of tables in order, and leaves at a port. That is the whole model.
The pipeline inside the bridge. A packet enters at a port, walks the tables in order, and leaves at a port. Service resolution and NetworkPolicy are both just tables in that sequence.
Two things are worth noticing about that sequence.
First, a Service is just a table. A ClusterIP is not an address that anything holds. No network card anywhere is configured with it. It is only something to match on. The packet arrives addressed to the ClusterIP, hits the table that handles Services, one backend pod is selected, and the destination is rewritten to that pod’s real address. Ping a ClusterIP and you may well get nothing back. That is not a fault. You are pinging something that was never meant to answer.
Second, NetworkPolicy is also just a table, and it sits in this same pipeline, right at the pod’s own interface. Where it sits matters more than it sounds, and it comes back later.
Three ways out, and that is all of pod networking
Once you can see the bridge, every packet a pod sends ends in one of exactly three ways. There is no fourth.
Every packet a pod sends ends one of three ways — and each one tells you where its policy belongs.
Destination
What happens
What that means
Pod on the same node
Straight out another port on the same bridge. The packet never reaches a vNIC at all.
Policy for this hop has to live where the traffic is: NetworkPolicy in the bridge, at the pod’s own interface.
Pod on another node
Out antrea-tun0, wrapped in a tunnel header, to the tunnel port on the other node.
At the vNIC it looks like UDP 6081 between two node addresses, so pod-level policy again belongs in the bridge.
Anything outside the cluster
Out antrea-gw0, then the node’s eth0, with the source address rewritten on the way.
The far end sees an infrastructure address instead of the pod, the same as any other masqueraded traffic.
That table is worth reading twice, because it tells you where to write policy. A firewall at the vNIC — on any platform, with any CNI — can only act on traffic it can see, and two of those three paths either never reach a vNIC or arrive inside a tunnel. So pod-level policy belongs at the pod’s own interface, which is exactly where Antrea puts it.
You can write it with kubectl, or author and audit it in NSX and let the Antrea–NSX adapter push it down. Either way the bridge is what enforces it, so you get one policy plane for pods whichever door you came in through. The controls at the vNIC stay for what they are genuinely good at: keeping one cluster’s nodes away from another’s, and limiting both to the Supervisor and the registry.
The three address blocks
The packet walk below needs three names, so here they are in the shortest useful form. An NSX VPC draws addresses from three separate blocks:
Block
What comes from it
Routable?
External
LoadBalancer VIPs, cluster API endpoints, outbound SNAT addresses
Yes — size this one deliberately
Private transit gateway
Addresses reachable across VPCs in the same project
Internally
Private VPC CIDR
Node VMs, and the slice of pod addresses given to each node
No
How those get allocated, and what you commit to on the Workload Network page of the activation wizard, deserves its own post. For now: VIPs come from External, pods and nodes come from the private VPC CIDR, and the VPC gateway sits between the two.
Exposing a pod: what a LoadBalancer Service really does
There are two separate stories here, and merging them is what makes this hard to explain. First an address gets allocated, which is a chain of controllers across three clusters and never touches a packet. Then a client actually connects.
Part one: allocation
The guest cluster has no load balancer controller of its own. When someone applies a Service of type LoadBalancer:
The paravirtual cloud provider, running on the guest cluster’s control plane, notices it. It holds scoped credentials to the Supervisor.
It creates a VirtualMachineService in the Supervisor namespace, selecting that cluster’s node VMs.
VM Operator turns that into a Service plus an Endpoints object whose members are the node VM addresses.
The NSX reconciler watches Supervisor Services and calls the NSX API. Classic deployments run NCP; VPC-mode builds may run the NSX VPC Operator instead. Worth checking which one you have, although the NSX objects are named with an ncp- prefix either way, so the naming will not tell you.
NSX creates a virtual server and a server pool on the VPC gateway, and allocates a VIP from the External block.
The address travels back down the same chain into the guest Service’s status.loadBalancer.ingress.
This is why <pending> is almost never a guest-cluster problem. There is no controller in that cluster that could allocate an address in the first place. If it is stuck, the chain broke further up. Check the VirtualMachineService in the Supervisor namespace first, then the NSX reconciler, then whether the External block has any free addresses left.
Part two: the packet
Now a client connects to the VIP. The left column is where the packet is. The right column is what its addresses look like at that exact point, with anything rewritten highlighted.
Four rewrites — and the one that destroys the client address happens at the load balancer, before Kubernetes ever sees the packet.
The rewrite that matters happens earlier than most people expect. The load balancer changes the source address as well as the destination, so the client’s address is already gone at the VPC gateway. That is before the packet has reached a node, and long before Kubernetes has any say in it. It is also why your access logs are full of the same address over and over.
What the pod sees as the source address
The standard advice is that externalTrafficPolicy: Local preserves the client’s address. On this path it does not. It only changes which infrastructure address the pod sees, and I only know that because I went and measured it.
First, where this setting actually lives
externalTrafficPolicy is a field on the Kubernetes Service. You set it with kubectl, in YAML, next to type: LoadBalancer. You never set it in NSX Manager. It is plain upstream Kubernetes, not a VMware addition, and it works the same way on EKS, GKE, OpenShift, or a bare-metal cluster running MetalLB. If you already know this setting from another platform, you know it here.
What is platform-specific is how the setting gets carried out. Choosing Local makes Kubernetes allocate a healthCheckNodePort. Every node then answers a simple health check on that port: 200 if it is running a pod for this Service, 503 if it is not. The controller that reconciles the Service turns that into two things on the load balancer, its pool membership and its health monitor. Nodes that answer 503 fail the check and stop receiving traffic.
So NSX Manager is where you see the result, not where you configure it. If you edit that pool by hand, it will be put back. The Service object is the source of truth.
Where externalTrafficPolicy sits. It controls the hop inside the cluster — the second rewrite, not the first. Addresses are from the lab measurement later in this post.
What each setting does
Cluster — the default
Every node accepts the traffic, whether or not it is running a pod for this Service.
If the chosen pod is on a different node, the packet is forwarded on, and the source is rewritten to antrea-gw0, the pod network’s gateway on the node that received it.
Load spreads evenly across pods. An extra node-to-node hop is common on clusters with several nodes.
The pod sees the pod network gateway.
Local — opt in
Only nodes actually running a pod for this Service answer, decided by the health check described above.
No extra hop and no second rewrite inside the cluster. Both are real benefits.
Traffic is spread across nodes rather than across pods, so uneven scheduling gives uneven load.
The pod still does not see the client. It sees the load balancer’s own address.
Here is the measurement, from an NSX VPC lab. Three replicas of traefik/whoami behind a LoadBalancer Service, called with curl from an admin host outside the cluster:
externalTrafficPolicy: Cluster
  RemoteAddr: 192.168.145.1     ← antrea-gw0, the rewrite inside the cluster

externalTrafficPolicy: Local
  RemoteAddr: 100.64.0.1        ← the VPC gateway load balancer

real client address
  never visible on this path at all
That node’s pod addresses came from 192.168.145.0/24, so .1 is its antrea-gw0. And 100.64.0.1 is not a guess. The NSX server pool for that Service shows SNAT Translation Mode: Automap, which replaces the source with the load balancer’s own address before handing the packet to a pool member. Every pool the reconciler creates has it set.
The virtual server is also plain TCP, on a Fast TCP profile, with no awareness of HTTP. So the source address the pod reads is the load balancer’s, not the caller’s. That is how any layer 4 load balancer doing source NAT behaves, on any platform, and it is exactly why terminating at layer 7 exists as a design pattern.
One clarification, because this is easy to overstate. The reconciler does create an HTTP profile on the same load balancer, alongside the TCP and UDP ones. The VPC load balancer is perfectly capable of layer 7. But that profile is used by virtual servers created from Ingress objects. A Service of type LoadBalancer always gets the layer 4 one. The limit is on the Service path, not on the load balancer.
The design consequence. The rewrite happens one hop before Kubernetes sees the packet, which makes this an architecture decision rather than a Service setting. The same is true of any layer 4 load balancer doing source NAT, wherever it runs. If an application needs the caller’s address, put something that terminates at layer 7 in front of the rewrite, where the client is still visible. Decide that alongside the ingress design, not when an application team asks the question.
This is worth stating plainly, because the usual Kubernetes advice about Local assumes a load balancer that is not rewriting the source. It is not a defect. It is the documented behaviour of a layer 4 virtual server whose pool is set to Automap. But it does mean Local buys you a shorter path and one less rewrite, not the client’s address.
Automap is a property of the pool, and NSX supports other modes, so in principle it is configurable. In practice these pools are created and maintained for you, so editing them by hand is not a supported workaround. Treat it as a property of the platform and design around it.
So when is Local worth setting?
Not for the client’s address. That is the whole point of the measurement above. But there are two honest reasons to use it. It removes a node-to-node hop, which is worth having on a latency-sensitive path and keeps that traffic off the tunnel between nodes. And it removes one layer of rewriting, which makes a packet capture much easier to read.
The cost is load distribution, and the arithmetic is worth doing. Take three nodes and four replicas: two on node B, one on node C, none on node A. The load balancer sees two healthy nodes and splits the traffic 50/50. Node B’s two pods share its half, so each gets a quarter. Node C’s single pod takes the other half on its own. That one pod is now handling twice the traffic of its peers, and nothing in Kubernetes will correct it. With Cluster, traffic spreads across all three nodes and then across all four pods, so each gets roughly a quarter, at the price of that extra hop.
So Local fits best where pod placement is already even by design: a workload that runs one pod per node, or one where you actually enforce a topology spread constraint. Set it on purpose, not by habit.
Verified two ways
What an application reports is suggestive, not proof. traefik/whoami tells you what its own socket says, which is one tool’s opinion. So I checked the same thing a completely different way, using Antrea Traceflow in liveTraffic mode. That captures the real frame inside the bridge instead of asking an application about it.
Two unrelated tools, the same two addresses. The load balancer’s Automap rewrite under Local, antrea-gw0 under Cluster, and in neither case the client.
The TTL is 123 in both captures. That is consistent with the rewrite inside the cluster being done by a rule in the bridge rather than being a routing hop. I used to present it as proof, and a reviewer was right to push back: an identical TTL does not prove no proxy was involved, because a proxy ends one connection and starts a new packet with its own TTL anyway. What actually settles it is the pipeline itself and the Traceflow capture, which show the packet being rewritten in the bridge with nothing in user space terminating anything. The TTL supports the conclusion; it does not carry it. (For the curious: starting from a Windows client’s 128, five hops were taken off on the way in, which matches the fabric, T0, transit gateway and VPC gateway.)
This also answers “can I see this flow with the product tooling?” Partly. Antrea Traceflow covers the half inside the guest and will capture live traffic. NSX Traceflow draws the overlay half, but cannot follow a VIP through the load balancer, because it injects a packet between two ports and a virtual server has no port to inject at. Neither tool does the whole path on its own. With the Antrea–NSX adapter registered, Antrea’s results appear in the NSX UI, which is the closest thing to one view across both.
The direction nobody asks about: outbound
Everything above is traffic arriving. Traffic leaving behaves differently, and it is routinely overlooked right up until a partner’s firewall gets involved.
A pod calling something outside leaves through antrea-gw0, out the node’s eth0, and through the VPC gateway, which rewrites the source again. So the mirror image of the client-address story applies: coming in, your pod cannot see who called it; going out, the far end cannot see which pod called them. Same mechanism, opposite direction. Neither is a fault. Both are what a rewrite does.
Which means that when a partner asks you to allow-list “the payments pod” at their firewall, by default you cannot. With the standard VPC gateway rewrite, the finest identity available at that boundary is the namespace, and only where Antrea Egress is in use. Without it, traffic leaves as the node’s address and even that distinction disappears.
Worth knowing that this ceiling has moved. VCF 9.1 supports Antrea Egress with the EgressSeparateSubnet feature gate, which takes egress addresses from a child segment instead of letting the VPC gateway rewrite them again. A chosen set of pods can then keep a dedicated, routable identity that NSX can match policy on. I have not tested this yet, so treat it as documented capability rather than a lab result. But if you have previously told a customer that namespace granularity is a hard ceiling, that answer now needs an asterisk.
One more thing worth saying plainly, because people assume the opposite: outbound traffic is not blocked by default. Nothing stops a pod reaching the internet unless you write policy that does.
Seeing it for yourself
Reading about address rewriting is far less convincing than watching it happen. Two demos, neither of which needs a packet capture.
Watch the allocation chain fire. Three terminals, then apply the Service in the first:
SUPERVISOR_NS=my-namespace

# T1 — guest cluster
kubectl get svc my-app -w

# T2 — Supervisor namespace
kubectl -n $SUPERVISOR_NS get virtualmachineservice,svc,endpoints -w

# T3 — the NSX reconciler. Find it first, the pod name varies by build:
kubectl -n vmware-system-nsx get pods
kubectl -n vmware-system-nsx logs -f <that-pod> --tail=50
T1 shows <pending>. T2 shows the VirtualMachineService appear, then the Service and Endpoints. T3 shows the reconciler working. Then T1 fills in. About fifteen seconds of wall clock, and the whole chain becomes obvious.
Prove the rewrite. This is the two-minute version that makes the entire packet diagram land:
kubectl create deploy whoami --image=traefik/whoami --replicas=3
kubectl expose deploy whoami --type=LoadBalancer --port=80
kubectl get svc whoami -w          # wait for EXTERNAL-IP

VIP=$(kubectl get svc whoami -o jsonpath='{.status.loadBalancer.ingress[0].ip}')

# Cluster (default): the rewrite inside the cluster
curl http://$VIP/                  # RemoteAddr = the pod network gateway
                                   # repeat — Hostname rotates across replicas

kubectl patch svc whoami -p '{"spec":{"externalTrafficPolicy":"Local"}}'

# Local: no rewrite inside the cluster — and still not you
curl http://$VIP/                  # RemoteAddr = the VPC gateway LB address
                                   # repeat — Hostname sticks to local backends
traefik/whoami prints both RemoteAddr and Hostname. Watch RemoteAddr change between the two runs. It moves from the pod network gateway to the load balancer’s address, and never to yours. That is a more interesting demo than the one I expected to be giving, because it shows the limit rather than a workaround.
If you want to go deeper, the tools split by layer: pktcap-uw on the ESXi host (use net-stats -l to find the switchport ID), plain tcpdump inside the node VM, and antctl inside the antrea-agent pod for the bridge itself. That last one is the most underused tool on the platform. It will show you the actual tables from the figures above, on your own cluster.
What I would actually do with this
Four design positions, ranked, with the one I would defend hardest first.
Size the External block against every consumer, not one. Count one VIP per guest cluster endpoint, one per LoadBalancer Service, and one outbound address per namespace, then add the growth rate of each. Everything else on this list can be fixed later. Running out of routable addresses mid-project cannot.
Put Services behind one layer 7 proxy instead of exposing each one. Ten microservices exposed as ten LoadBalancer Services is ten routable addresses. Behind one ingress it is one. Note what this does not buy you: an ingress inside the cluster still sits downstream of the VPC gateway rewrite, so it cannot see your client either. Consolidate for the address economics and the routing, not for the client’s address.
Be generous with private VPC CIDRs. They are free, they can repeat across VPCs, and a tight range is what stops a cluster growing eighteen months from now, when nobody remembers why the number was chosen.
Decide the pod-level security story explicitly, and early. Pod-to-pod traffic is enforced at the pod’s own interface, which is what the three-ways-out table means in practice. Either you accept NetworkPolicy inside the cluster as the enforcement point, or you deploy the Antrea–NSX adapter so those same policies are authored and audited from NSX. Both are defensible. Finding out which one you have during a security review is not.
None of this is exotic. It follows from a layered platform where each layer does its own job well and none of them can see the others. Once you can hold the whole path in your head at once, the policy question, the source-address question and the address-planning question all turn out to be the same picture from different angles.
Written against VCF 9.1, with the data-plane addresses measured in a live lab rather than assumed. The TTL argument in an earlier version of this post was overstated and has been corrected here. Defaults and object names move between releases, so verify against the version in front of you before designing to them. Corrections and disagreements welcome. I would rather fix this than have it be quietly wrong.
If you administer vSphere, you already know how to build a VM. This post shows you how to build the same VM in VMware Cloud Foundation Automation using nothing but a command line — no UI clicks, no cloud template, no prior Kubernetes experience assumed. It takes about less then 10 minutes, and by the end you’ll have a running web server with a load-balanced IP that answers from your browser.
I’m deliberately keeping this simple. There is a longer, deeper reference post for the full API surface, but this one is the on-ramp: the shortest honest path from “I’ve never used the VCF Automation API” to “I just built something with it.”
What we’re going to do
Install the CLI and log in to your organization
Create a project (the tenancy boundary for a team)
Create a Supervisor Namespace (where workloads actually live)
Create a VM with cloud-init that installs nginx
Publish it behind a load balancer and browse to it
Build a Kubernetes cluster in the same namespace, and run a workload on it
Why bother, when the UI works fine?
Fair question, and I’d give three honest answers.
Repeatability. A VM you clicked into existence is a VM nobody can rebuild exactly. A VM defined in a YAML file is one you can commit, review, and recreate identically a year later.
It’s where the platform is going. In VCF 9, the consumption layer is a Kubernetes-style API. The UI is a client of that API, not the other way round. Learning the objects underneath means the UI stops being magic.
It’s the foundation for automation. Everything you’d want later — GitOps, pipelines, self-service catalogs — is built on these same objects. This is the first rung.
None of that means you should stop using the UI. I use both. But knowing what’s underneath makes you considerably harder to stump.
Before you start
What
Where to get it
VCF CLI (the vcf command)
Broadcom Support portal — it replaces the older CCI kubectl plugin
kubectl
Any recent version; the CLI generates a kubeconfig for it
An API token
Log into your VCF Automation org portal → your user menu → API Tokens → Generate. Copy it — it’s shown once.
Org admin rights
Needed to create projects. If you only have consumer rights, skip to Step 4 and use an existing namespace.
Everything below is run from PowerShell on Windows. It works identically on Linux and macOS; only the quoting changes.
Step 1 — Log in
First, store your token in a variable. Note the quotes — without them PowerShell tries to execute the token as a command, which produces a confusing error.
$vcfa_token = "your-api-token-here"
Now create a context. This is the CLI’s word for “a saved connection to an environment.”
Substitute your own endpoint and tenant name. The backtick is PowerShell’s line-continuation character — or just put it all on one line. Use --insecure-skip-tls-verify only in a lab; in production supply your CA certificate with --ca-certificate instead.
A successful login. Note that the CLI lists every context you now have access to — one for the organization, plus one for each Supervisor Namespace you can reach.
That output is worth reading carefully, because it explains the whole model. You get an organization context (org2-ctgw) and a namespace context for each namespace you can use (org2-ctgw:org2-ns1-4hm32:default-project).
The one concept to take away
There are two levels. The organization context is where you manage tenancy — projects, namespaces, who gets what. The namespace context is where you build things — VMs, clusters, networks. Almost every “why can’t I see that?” moment is being in the wrong one. If a command returns “the server doesn’t have a resource type”, you’re at the org level asking a workload question.
Step 2 — Create a project
A project is the boundary you’d hand to a team. Save this as project.yml:
apiVersion: project.cci.vmware.com/v1alpha2
kind: Project
metadata:
  name: team-phoenix
spec:
  description: Phoenix dev team
kubectl --context org2-ctgw create -f project.yml
# project.project.cci.vmware.com/team-phoenix created
Use create, not apply
This will save you a puzzling ten minutes. kubectl apply stores a tracking annotation on the object, and this API rejects it outright with “Annotation updates are not supported.” Everywhere in this post, use kubectl create.
Step 3 — Create a namespace
The project is just a boundary. A Supervisor Namespace is the thing with actual capacity — CPU, memory, storage, a network — where your VMs will live. Think of it as the resource pool plus the network plus the quota, expressed as one object.
You need four pieces of information, all of which you can read off an existing namespace or get from whoever set up your environment:
Two things that catch people here
The namespace name is generated with a random suffix (phoenix-ns-kj9g6), so read it from the previous command rather than guessing. And the context name is the full three-part string <org>:<namespace>:<project> — using just the namespace name gives you “no context exists.”
You can confirm the same thing in the UI, which is a reassuring way to check your work while you’re learning:
The namespace created from the command line, shown in the VCF Automation UI — Active, in the team-phoenix project, with its CPU, memory and storage allocation. The API and the UI are two views of the same object.
Why the long classConfigOverrides block?
When you create a namespace through the portal, it fills these values in for you from the class. Creating one through the API, you have to state them yourself — and the zone entry needs all four CPU and memory fields, not just a name. If you leave them out, the API tells you exactly what’s missing, one field at a time. That’s actually a decent way to learn the object: submit a minimal version and let the error messages guide you.
Step 4 — Create a VM
Now the part that will feel familiar. We need three things: a size, an image, and a storage policy. Ask the namespace what it has:
kubectl get virtualmachineclasses     # the sizes available to you
kubectl get virtualmachineimages      # images from your content library
kubectl get clustervirtualmachineimages | Select-String "ubuntu"
If virtualmachineimages comes back empty, you’re not stuck.
That list is empty when no content library is attached to your namespace class. You can still deploy from a cluster-wide image by referencing its vmi- identifier directly, which is what I do below. Getting a content library attached is the better long-term answer — it gives you friendly names instead of hashes — but it isn’t a blocker today.
Here’s the VM, together with a cloud-init secret that creates a login and installs nginx. Save both in one file:
Two objects, one command: the cloud-init secret and the VM itself.
Watch it come up. The VM will report an IP address once VMware Tools starts reporting:
kubectl get vm web01
kubectl get vm web01 -o jsonpath='{.status.network.primaryIP4}'
# 172.30.0.66
Notice what you didn’t have to specify: no port group, no IP address, no datastore. The VM picked up an address from the namespace’s default network automatically and landed on storage matching the policy you named. That’s the platform doing the placement work, exactly as it does for a Kubernetes pod.
Cloud-init only runs on first boot
You cannot add a bootstrap section to a VM that already exists. If you forget it, the VM boots fine but has no user account and no way in — you delete and recreate. Decide your bootstrap before you provision.
Step 5 — Publish it
A VirtualMachineService puts a load-balanced IP in front of one or more VMs, selected by label. Our VM carries app: web, so the service will find it.
The load balancer service, created. NSX allocates the external address within seconds.
Reading the external IPkubectl get vmservice prints only name, type and age — the address isn’t in its default columns. Use kubectl get svc instead, or ask for the field directly with -o jsonpath='{.status.loadBalancer.ingress[0].ip}'.
Step 6 — Confirm it works
kubectl get svc
# web-lb   LoadBalancer   172.29.255.24   40.60.0.4   80/TCP   2m31s

kubectl get endpoints
# web-lb   172.30.0.66:80   2m34s

curl.exe http://40.60.0.4
The whole chain proven: external IP 40.60.0.4, backend 172.30.0.66:80, and nginx answering.
That’s the full path working. The load balancer address is allocated from the NSX VPC, the endpoint is your VM’s own IP, and nginx — installed by cloud-init at first boot — is serving. Nothing in that sequence involved the UI.
Step 7 — Build a Kubernetes cluster
Here’s the part that surprises people: a Kubernetes cluster is just another object in the same namespace you’ve been working in. Same context, same kubectl create, same mental model. You describe the cluster you want and the platform builds the nodes.
You need to know two things first — and both are places where a sensible-looking manifest fails.
Where the cluster template lives. Clusters are built from a ClusterClass, which is a template your platform team maintains. Crucially, it does not live in your namespace:
kubectl get clusterclasses
# NAME                     VARIABLES READY   AGE
# builtin-generic-v3.1.0   True              164m
# builtin-generic-v3.2.0   True              164m
# builtin-generic-v3.3.0   True              164m
That list is not the whole story. The class you actually want may live in a shared system namespace and won’t appear here at all — you reference it explicitly by name and namespace.
Which Kubernetes version you can use. Ask the platform rather than guessing:
kubectl get kubernetesreleases
You’ll get a long list. Only the rows showing bothREADY: True and COMPATIBLE: True are usable. Pick one of those.
Now the cluster itself — one control plane node, one worker, deliberately small:
kubectl create -f cluster.yml
kubectl get cluster phoenix-k8s -w
Provisioning takes five to six minutes for this size. PHASE: Provisioned appears early and only means the objects were created — the column to watch is AVAILABLE, which flips to True once the control plane is genuinely up. kubectl get machines gives you the per-node view while you wait.
Three things in that manifest are not obvious1.classRef needs a namespace. The ClusterClass lives in a shared system namespace, and without it you’ll get a “not found” even though the class plainly exists. 2. The version string is the long form — v1.35.5---vmware.1-vkr.1, with three dashes, not the +vmware.1 form shown elsewhere. 3. The resolve-os-image annotation is often required. If your environment has the same node image registered in more than one content library — common in labs that have been upgraded a few times — the resolver refuses to guess and fails with “Multiple OSImages resolved.” Adding content-library= narrows it to one. You’ll find the library ID in your Content Libraries list.
The shortcut worth knowing
Rather than assembling this by hand, start a cluster creation in the VCF Automation UI and look at the YAML it generates. It will show you the right ClusterClass namespace, the right version format, and any annotations your environment needs — all correct for your specific build. Copy that, then edit it. This is far quicker than reverse-engineering from error messages, and it’s how I arrived at the manifest above.
Step 8 — Get onto the cluster and run something
Once AVAILABLE is True, download the cluster’s kubeconfig from the VCF Automation UI (the cluster’s detail page offers it) and point kubectl at it:
kubectl --kubeconfig .\phoenix-k8s.yaml get nodes
# NAME                        STATUS   ROLES           AGE   VERSION
# phoenix-k8s-...             Ready    control-plane   12m   v1.35.5+vmware.1
# phoenix-k8s-...-np-1-...    Ready    <none>          9m    v1.35.5+vmware.1
You’re now a cluster administrator on an ordinary, conformant Kubernetes cluster. Everything you know about Kubernetes applies from here.
With one important exception, which is worth meeting deliberately rather than by accident.
Your first deployment will probably be rejected — and that’s correct
Try the obvious thing:
kubectl --kubeconfig .\phoenix-k8s.yaml create deployment web --image=nginx --replicas=2
The deployment is created, but no pods ever appear. Looking at the ReplicaSet tells you why:
pods "web-..." is forbidden: violates PodSecurity "restricted:latest":
  allowPrivilegeEscalation != false
  unrestricted capabilities (must set capabilities.drop=["ALL"])
  runAsNonRoot != true
  seccompProfile (must set seccompProfile.type to "RuntimeDefault")
This is Pod Security Admission enforcing the restricted profile, and it’s switched on by default. A stock container image that runs as root is refused at creation — not warned about, refused. For a vSphere admin used to “deploy first, harden later,” this is a genuine change of habit, and a welcome one: the cluster will not run a privileged workload just because you forgot.
The fix is to declare what the workload actually needs. Each field below answers one of the four complaints, and the image is swapped for a non-root variant that listens on 8080 rather than binding port 80 as root:
kubectl --kubeconfig .\phoenix-k8s.yaml apply -f web.yml
kubectl --kubeconfig .\phoenix-k8s.yaml expose deployment web --port=80 --target-port=8080 --type=LoadBalancer
kubectl --kubeconfig .\phoenix-k8s.yaml get svc web
The external IP is allocated by the same NSX load balancer that served your VM in Step 5 — usually within seconds. Confirm there are backends behind it:
Note that kubectl apply works here.
The “use create, not apply” rule applies to the VCF Automation API only. Inside a VKS cluster you’re talking to a normal Kubernetes API server, and all your usual habits — apply, Helm, Kustomize — work exactly as expected.
The five things that will trip you up
These cost me time so they don’t have to cost you any.
Use kubectl create, never apply. The API rejects the annotation that apply depends on.
Context names are three parts.<org>:<namespace>:<project>, not just the namespace.
Know which level you’re at. “The server doesn’t have a resource type” almost always means you’re at the org context asking a workload question, or vice versa.
Tokens expire mid-session. A sudden Unauthorized, or a strange complaint about downloading the OpenAPI schema, usually just means your session lapsed. vcf context use <org> re-authenticates.
Check the API version against your build. Published examples lag. On the environment used here, namespaces are served at v1alpha3 and VMs at v1alpha5. The most reliable way to learn the current shape of any object is to dump a working one: kubectl get vm <name> -o yaml. Copy the structure, change the values.
That last one is worth internalising as a general habit. Rather than hunting for documentation that matches your exact release, clone something that already works in your own environment. It is always correct, by definition.
Where to go next
You now have the pattern for everything else on this platform. The same two-level model, the same create workflow, and the same “clone a working object” trick apply to Kubernetes clusters, persistent volumes, NSX security policies, and micro-segmentation rules — all of which are just more objects in the same API.
A few natural next steps, in the order I’d take them:
Delete and rebuild what you just made. Change the VM size in the YAML, recreate, and watch it come back identically. That’s the payoff of declarative infrastructure, and it’s more convincing when you do it than when you read about it.
Scale the cluster. Change replicas on the worker pool, re-apply, and watch nodes roll in. Then bump version to a newer compatible release and watch a rolling upgrade — that’s a one-line change doing something that used to be a project.
Write a security policy as YAML and watch NSX distributed firewall rules appear.
Put it all in Git. Once your infrastructure is files, a GitOps engine can reconcile it. That’s the subject of my next post.
If you’re a vSphere admin who has been eyeing all this with mild suspicion, I’d encourage you to run through the steps above once in a lab. The concepts are less foreign than the vocabulary suggests — a namespace is a resource pool with a network and a quota, a VM is still a VM, and a load balancer service is the thing you’d have raised a ticket for. The difference is that now it’s a file you own.
Questions or something that didn’t work in your environment? Leave a comment — I read all of them, and environment-specific quirks are exactly what makes these posts better.
Every so often a platform capability arrives that your workloads benefit from without a single line of configuration. Memory Tiering under vSphere Kubernetes Service (VKS) is exactly that: enable it once at the cluster level, and every Kubernetes node — and every pod on it — inherits smarter memory economics automatically. No drivers, no manifest changes, no separate policy for containers. Broadcom has now published testing that confirms it works for VKS just as well as it does for VMs. Here is what the feature actually does, why the Kubernetes inheritance is the interesting part, and how to put it to work.
TL;DR for the busy architect:
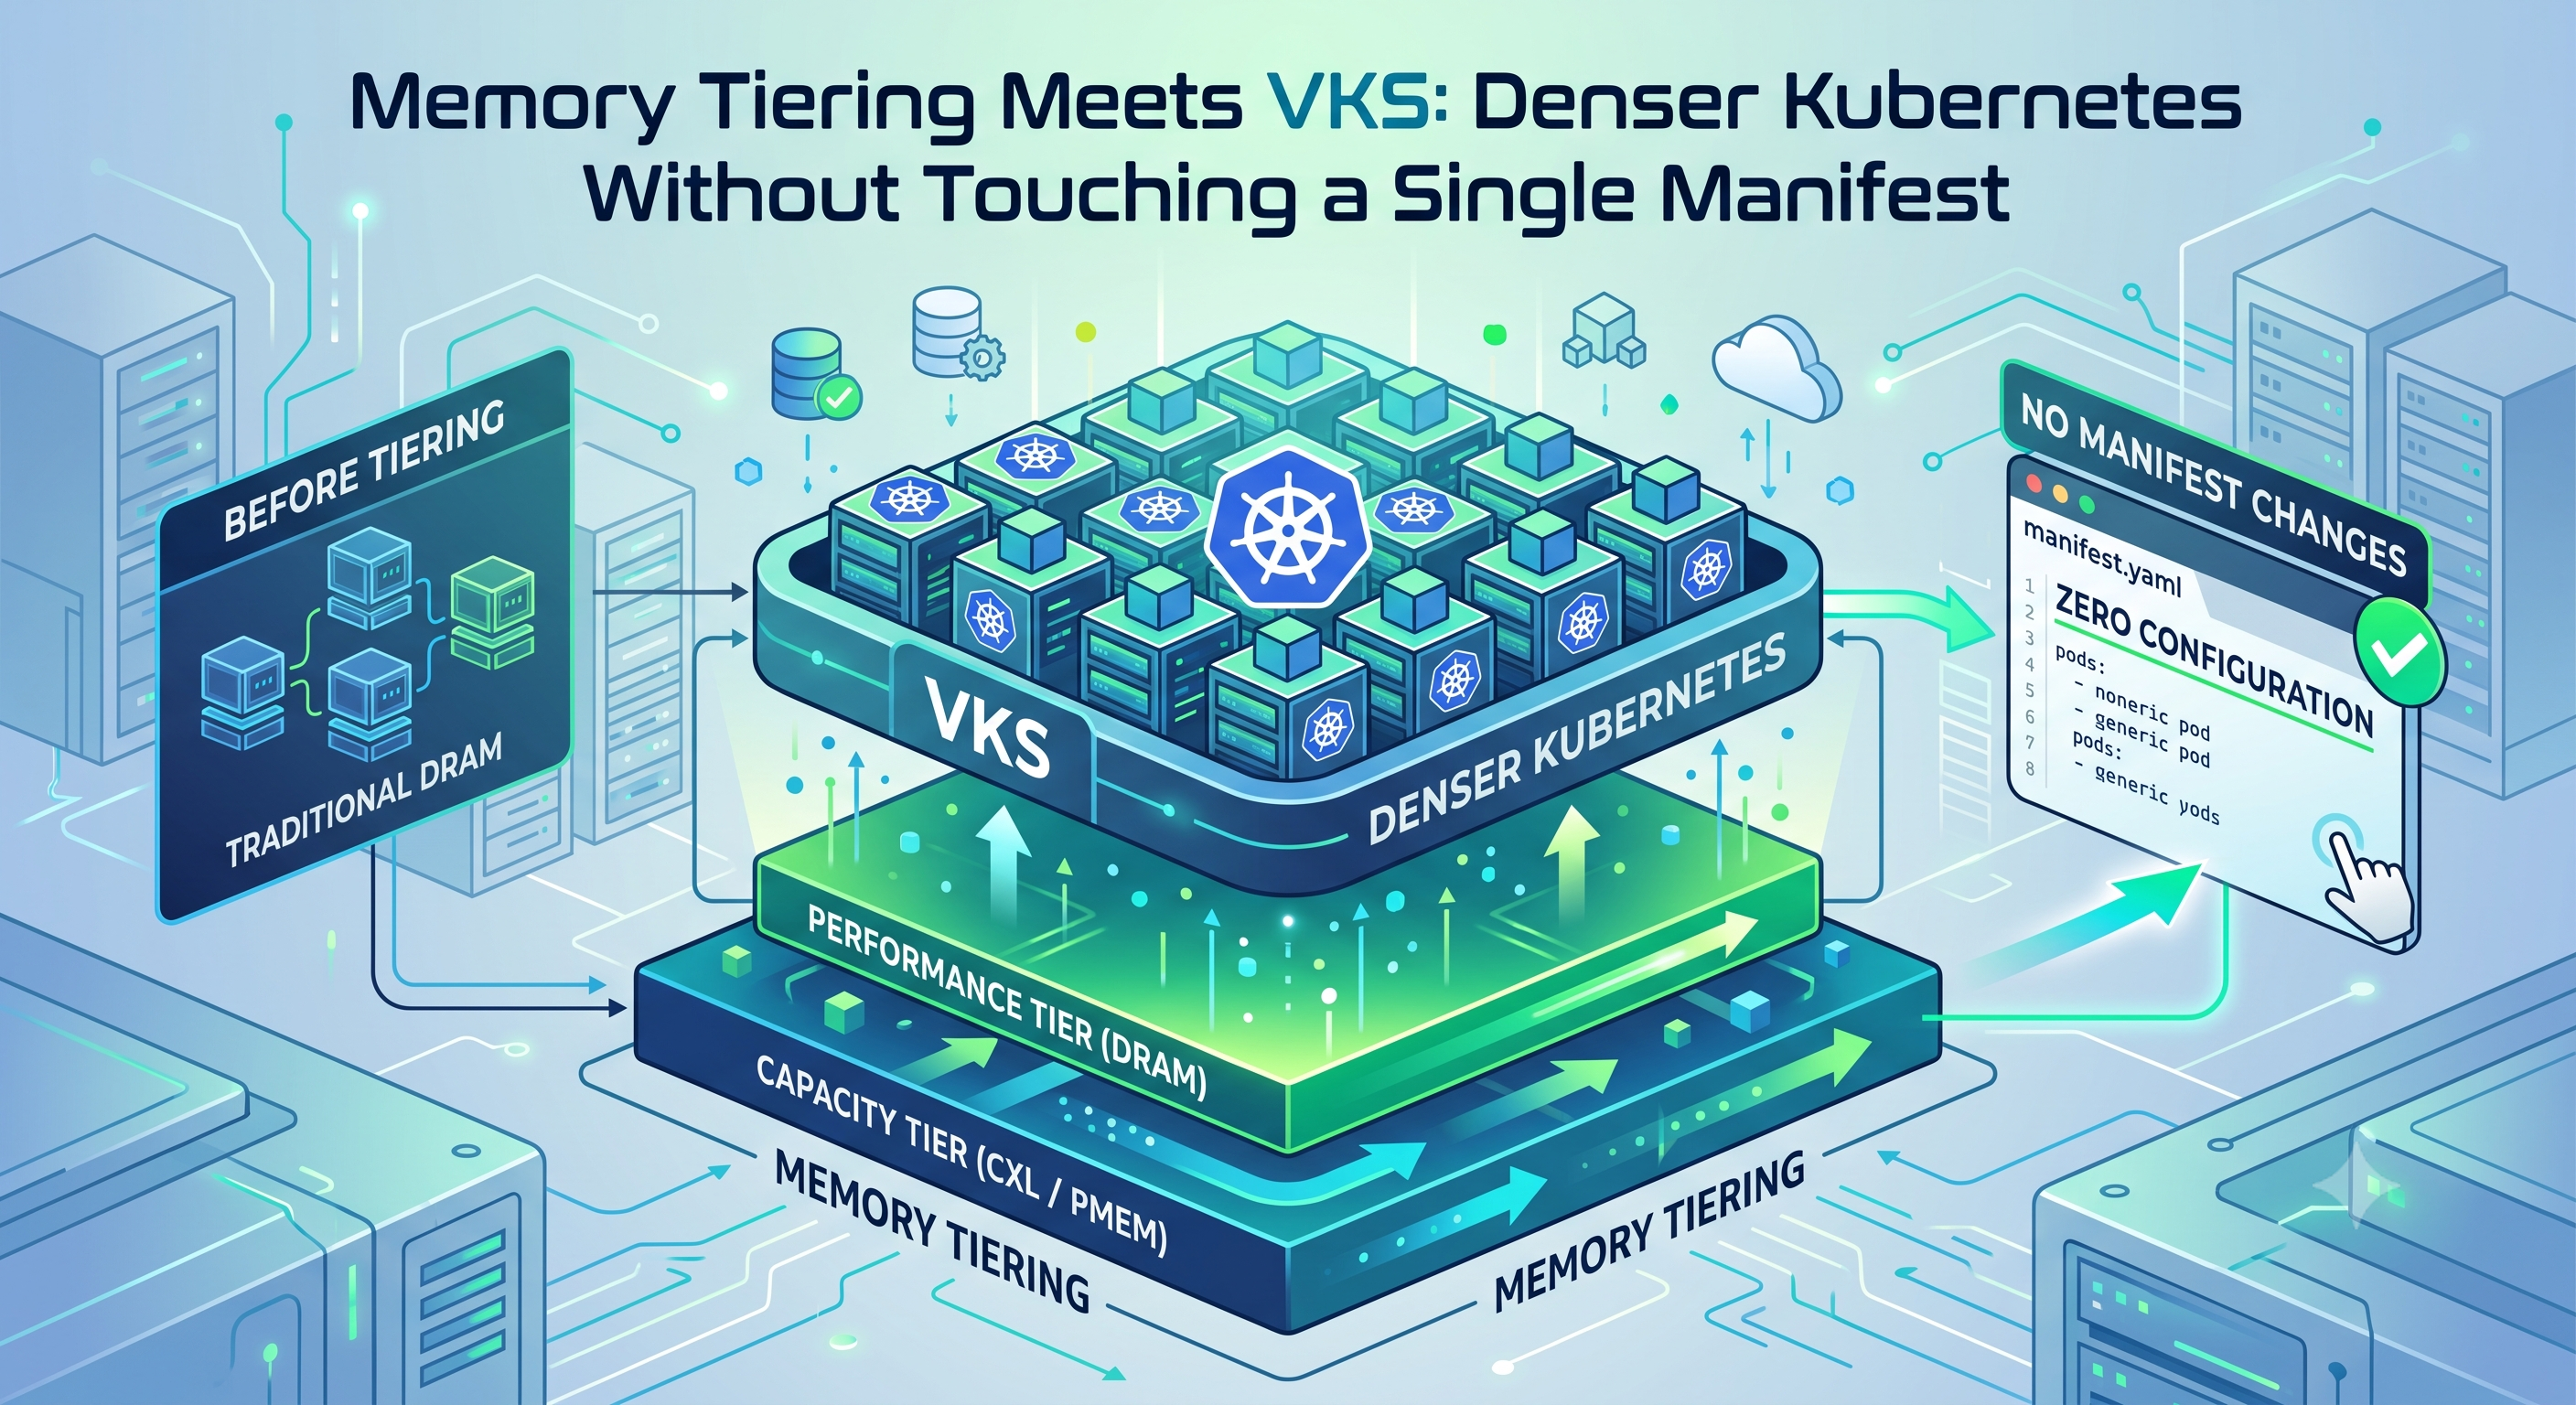
Memory Tiering lets an ESXi host combine DRAM with an NVMe-backed second tier into one memory pool — hot pages stay in DRAM, cold pages move to NVMe, and pages promote back automatically when touched.
Because VKS worker nodes are VMs on that same hypervisor, Kubernetes inherits the capability transparently — nothing above the hypervisor needs to know it exists.
The payoff: more worker nodes per host, a smaller DRAM footprint for your Kubernetes estate, and one capacity model that covers VMs and containers together.
Broadcom’s validation shows VKS workloads on tiered hosts performing in line with VM workloads — so the sizing guidance you already use for VMs extends to Kubernetes with confidence.
It is a workload-class decision, not a global switch — the “where it fits” section below matters as much as the feature.
The quiet memory problem every Kubernetes platform team knows
Kubernetes schedules pods on requests, and requests are set defensively. The app team asked for 4 GiB “to be safe,” the Helm default was generous, and nobody wants to own the OOMKill. Multiply that across hundreds of pods and every production cluster carries a wide gap between the memory workloads reserve and the memory they actually touch. Platform teams fight this with rightsizing dashboards and VPA recommendations — worthy work that never quite ends, because it treats the symptom: the reservation. The reserved-but-cold memory itself still sits in expensive DRAM.
What if the infrastructure could simply handle cold memory differently from hot memory — without Kubernetes, the node OS, or the application having to participate?
What Memory Tiering actually does
Memory Tiering in VCF 9 lets an ESXi host present a single memory pool built from two tiers: fast DRAM and an NVMe device configured as a memory extension. The hypervisor watches page access patterns and manages placement automatically:
Hot pages stay in DRAM. Actively-touched memory lives where latency matters.
Cool pages move to the NVMe tier. Reserved-but-idle memory stops occupying your most expensive resource.
Touched pages promote back. If a cooled page becomes active again, it returns to DRAM — the process is continuous and automatic.
The crucial design point is where this happens: below the guest OS, below the Kubernetes node VM, below the container runtime. The workload sees one contiguous memory space. There is no driver to install, no kernel parameter to tune, and no application change required. And the economics follow naturally — enterprise NVMe capacity costs a fraction of DRAM per gigabyte, and NVMe bays are plentiful where DIMM slots are finite.
The VKS part: inheritance for free
Here is the architectural elegance that makes this a Kubernetes story. A VKS worker node is a VM running on the same vSphere infrastructure as everything else. So when you enable Memory Tiering on a VCF cluster, your Kubernetes nodes inherit it the moment they land there — exactly as your VMs do. The Kubernetes scheduler keeps making its decisions against each node’s advertised capacity, exactly as before. ESXi, underneath, manages page temperature. Kubernetes manages reservations; the hypervisor manages reality. Each layer does the job it is best at, and neither needs to know about the other.
Contrast that with what this would take anywhere else: per-node OS tuning, kernel-version dependencies, careful coordination with the container runtime, and a Kubernetes-specific memory policy to maintain forever. Under VKS it is one setting, applied at the infrastructure layer, covering your entire fleet — VMs and clusters alike.
The fair question has always been whether the container layer changes the story — Kubernetes workloads are dense, churny, and allocation-happy. Broadcom put exactly that question to the test in their July 2026 post Memory Tiering for VMs and VKS, running database benchmarks on tiered hosts with half the DRAM of the baseline. The finding that matters: VKS workloads performed in line with the equivalent VM workloads, staying close to the full-DRAM baseline within the published sizing guidance. The Kubernetes layer neither breaks nor degrades the feature. Their numbers and test parameters are in the post, with deeper sizing detail in the Memory Tiering performance whitepaper.
The picture
How it helps: four practical wins
1. More worker nodes per host, without buying DRAM. Memory — not CPU — is the binding constraint on most Kubernetes host density. Tiering raises the addressable memory per host using NVMe capacity, which means more (or larger) worker VMs on the same hardware. Your cold-page-rich container estate is precisely the workload profile this was built for: hundreds of defensively-sized pods generate exactly the reserved-but-idle memory that tiers gracefully.
2. A smaller DRAM footprint for the same Kubernetes estate. Flip the same coin: instead of packing more onto big hosts, run the estate you have on hosts with less DRAM. That matters most where DIMM slots are the constraint — edge sites, dense chassis, or refresh cycles where high-capacity DIMMs dominate the bill of materials. Because VCF licensing is per-core, capacity gained through memory density adds nothing to the software line — a point worth one sentence in any business case, even a feature-focused one.
3. One capacity model for VMs and containers. This is the quietly valuable one for platform teams. Broadcom’s validation means the sizing and tiering guidance you use for VM workloads extends to VKS workloads — one set of recommendations, one configuration, one capacity plan for a mixed fleet. No Kubernetes-specific memory policies to author, document, and maintain alongside your VM standards.
4. Zero change to the things you least want to touch. No application code, no container images, no Kubernetes manifests, no node OS tuning. For a platform team, features that require app-team cooperation move at the speed of your slowest app team; features that live below the stack move at the speed of a maintenance window. This one lives below the stack.
Where it fits — and where it doesn’t
An honest feature guide names the boundaries. Memory Tiering is a workload-class decision:
Hot working sets don’t tier. The benefit comes from cold pages. In-memory databases, Redis, Kafka page cache, JVM heaps under sustained load — workloads that touch most of what they allocate — keep their pages in DRAM, and tiering buys little on those nodes. Plan node pools accordingly rather than expecting uniform gains everywhere.
Latency-critical pods deserve DRAM guarantees. A page served from NVMe is fast by storage standards and slow by memory standards. Keep tail-latency-sensitive services on untiered or conservatively tiered hosts, and steer them there with the taints and node selectors you already use — your existing Kubernetes scheduling machinery is exactly the right control surface.
Respect the published guardrail. The official guidance keeps active memory comfortably within DRAM capacity — the working set, not the addressable total, is your design boundary. Start with conservative tier ratios, observe real page-temperature behavior, then extend.
It complements rightsizing; it doesn’t replace it. Tiering does not change what the Kubernetes scheduler sees — which is the point — but that also means inflated requests still strand schedulable capacity. Keep the rightsizing hygiene; let tiering absorb what hygiene can’t reach.
A practical adoption path
Step
Action
Output
1
Baseline active vs. consumed memory across VKS clusters in VCF Operations
Enable tiering on one tiering-friendly host group at a conservative ratio
Real page-temperature data from your workloads
4
Validate application SLOs and node stability through a full business cycle
Go/no-go evidence per workload class
5
Extend host group by host group, re-baselining as you go
A fleet-wide rollout grounded in your own data
The bottom line
The strongest features are the ones your workloads don’t have to know about. Memory Tiering under VKS is a hypervisor capability that Kubernetes inherits simply by running where it runs — hot pages in DRAM, cold pages on NVMe, everything transparent above the hypervisor line. For platform teams it means denser hosts or leaner DRAM configurations, one capacity model across VMs and containers, and not a single manifest changed. VKS already removes the operational overhead of running Kubernetes beside your VM estate; Memory Tiering quietly removes a good part of the DRAM overhead of running it at scale.
Start with the baseline in VCF Operations — the gap between active and consumed memory on your clusters is the feature’s opportunity in your environment, measured. Everything after that is a controlled rollout.
Are you running Memory Tiering under VKS yet — or planning to? I would love to hear which workload classes you are tiering first, and what your active-vs-consumed gap looks like in practice. And if there is interest, a tiering-readiness calculator in the style of my other VCF tools might be the natural follow-up.
VKS on VCF 9.1What Actually Changed & Why It Matters
A Comic Book Story in Seven Chapters
Issue #01 · May 2026 · The VCF 9.1 Saga
⚡ Cast of Characters ⚡
Captain VKS
vSphere Kubernetes Service 3.6
The hero. Born from vSphere, forged in CNCF conformance. Now powered up with VCF 9.1 abilities.
The Architect
Platform Engineer
Our protagonist. Runs multi-domain VCF estates. Needs Kubernetes at enterprise scale without the circus.
Cluster Creep
The Villain of Sprawl
Feeds on operational toil, slow provisioning, and fragmented toolchains. Grows stronger with every manual step.
The Oracle
VCF Operations 9.1
Sees all. Knows cost. Tracks every namespace. Speaks in metrics and FinOps.
🥊 The Challengers 🥊
The Cloud Twins
The Hyperscaler Duo
They move fast and always whisper: “Just move to our cloud.” They charge per hour and never let go.
The Red Baron
The Opinionated Platform
Arrives in full armor. Brings his own runtime, registry, mesh, and opinions about everything. Enterprise prices included.
The Wrangler
The Multi-Cluster Cowboy
Rides across any ranch — any cloud, any edge, any distro. Freedom is his creed. But who’s managing the cattle?
Bare Knuckle
The DIY Brawler
No platform. No hand-holding. Bare metal, kubeadm, and grit. Cheap up front. Costs you in blood and 3 AM pages.
Chapter 01The 37-Minute Nightmare
The data center. 6:42 AM. The Architect stares at a provisioning timer that refuses to move. Cluster Creep watches from the shadows, feeding on frustration.
The Architect
37 minutes to spin up a dev cluster. Thirty. Seven. Minutes. The hyperscaler team next door gets theirs in ten. The CTO is asking questions.
Cluster Creep
Yesss… and that’s just the deployment. Wait until you see the upgrade windows. I’ve got 45 minutes of downtime planned for each cluster. You have 200 clusters. Do the math. 😈
That’s 150 hours of maintenance windows per upgrade cycle… across the fleet…
May 5, 2026. Broadcom releases VCF 9.1. And everything changes.
Captain VKS
Miss me? I brought Fast Deploy. Let me show you the new numbers.
Metric
VCF 9.0
VCF 9.1
Cluster Deploy Time
37 min
11 min (↓69%)
Cluster Upgrade Time
45 min
15 min (↓67%)
Max Clusters / Supervisor
~100
500
Node Pool Placement
Manual
DRS Intelligent
Chapter 02The Challengers Step Forward
Word of VCF 9.1 spreads. Four challengers emerge from the fog, each claiming the throne of enterprise Kubernetes. The Architect has heard their pitches before.
The Cloud Twins
Adorable upgrade, Captain. But we’ve been doing sub-10-minute clusters for years. Managed control plane. Global regions. Auto-scaling node groups. Why fight gravity? Just come to the cloud.
Captain VKS
Sure — and your managed control plane costs how much per cluster per month? Multiply that by 500 clusters. Now add the egress fees. Now add the data sovereignty audit your CISO just mandated. I run on hardware you already own.
The Red Baron
How charming. You finally got CNI choice? I ship with my own SDN, my own service mesh, my own registry, my own CI/CD pipelines, and a full developer portal. I am the platform. You’re still assembling one.
Captain VKS
You are the platform. That’s the problem. Your opinions become my constraints. Your lifecycle becomes my upgrade treadmill. Your per-core subscription becomes my CFO’s nightmare. I give choice. You give mandates.
The Wrangler
Y’all are so cute with your single-vendor stacks. I run on any infrastructure. True multi-cluster freedom. No lock-in. Ever.
Captain VKS
Freedom is great until your team is maintaining six different infrastructure backends. I give you 500 clusters on one Supervisor with one operational model. You give them options and a prayer.
Bare Knuckle
I don’t need a platform. kubeadm, a Makefile, and raw skill. Zero licensing. Zero overhead. Pure Kubernetes.
Captain VKS
I respect the craft. But who patches your nodes at 2 AM? Who handles etcd backups? Who runs certificate rotation? Your “zero cost” platform costs three full-time engineers.
The Architect
I’ve evaluated all of you. Here’s my problem: I already run VCF. My VMs, NSX networking, vSAN storage, and security policies are all here. I need Kubernetes that joins my platform — not one that replaces it or ignores it.
The best Kubernetes platform is the one that doesn’t make me build a second operations team…
Chapter 03Fast Deploy — 11 Minutes or Bust
Captain VKS explains what changed under the hood. Fast Deploy isn’t a marketing stunt — it’s an architectural rework of the provisioning pipeline.
Captain VKS
Here’s what actually happened. We parallelized the node bootstrapping sequence, pre-staged container images into a local content library, and eliminated redundant API round-trips during cluster init. 11 minutes, from API call to workload-ready.
The Architect
What about upgrades? That’s where we bleed. Every cluster upgrade is a maintenance window, and my team juggles 200+ clusters.
Captain VKS45 minutes down to 15. Pre-staged images, parallel node drain-and-replace, and Multiple Clusters per Zone means you keep workloads running on Zone A while upgrading Zone B.
⚡ IMPACT METER ⚡
Provisioning Speed Gain
69%
Upgrade Speed Gain
67%
Scale Ceiling Increase
5× (500 clusters)
The Cloud Twins
11 minutes… fine, that’s competitive. But can you match our global availability zones?
Captain VKS
I don’t need 60 regions. My Architect’s data stays in his sovereign data center, on his hardware, under his compliance umbrella. Your 60 regions are 60 places his CISO has to audit.
Chapter 04DRS Strikes Back — Intelligent Node Pool Placement
VCF 9.1 introduces Intelligent Node Pool Placement. This isn’t basic affinity rules — it’s DRS-level scheduling applied to Kubernetes node pools.
Captain VKS
GPU pods → GPU hosts. NVMe workloads → NVMe nodes. DRS algorithm decides placement — not your YAML-wrestling platform team.
The Red Baron
I have Topology Manager, NUMA-aware scheduling, and a full operator ecosystem. Infrastructure-aware placement is table stakes for me.
Captain VKS
You schedule within the cluster. I schedule the cluster itself. DRS sees the whole estate. Your scheduler sees one namespace.
The Oracle
With VKS Cost Showback in VCF Operations 9.1, I can tell you exactly what each namespace, each cluster, each team is costing you. FinOps FOCUS-compliant.
The Oracle
I also expose an API for your RAG pipelines and MCP frameworks — your AIOps engine can query cost data directly.
Per-NS
Cost Attribution
FOCUS
FinOps Compliant
Real-Time
Pricing Estimates
Show + Charge
Back Capability
Chapter 05Container-as-a-Service & The CNI Revolution
VCF 9.1 introduces a simplified Container Service — deploy containers without deep Kubernetes expertise. Meanwhile, VKS 3.6 opens up CNI choice for the first time.
Captain VKS
First: Container-as-a-Service. Your app teams get a self-service surface. Click, deploy, done. No Supervisor clusters or ClusterClass YAML.
Captain VKS
Second: CNI freedom. VKS 3.6 deprecated ClusterBootstrap. Pick your CNI through the Addon Framework using AddonConfig CRDs. Antrea default, but the door is open.
The Wrangler
Oh, you’re just now letting people choose their CNI? Welcome to 2022, Captain.
Captain VKS
You let them choose. I let them choose with validated blueprints, lifecycle support, and a single vendor to call at 3 AM. Choice without support is just risk with extra steps.
The Architect
And the Ingress story? The popular open-source Ingress controller is being retired…
Captain VKSAvi Load Balancer — natively integrated. Centralized control plane, distributed data plane, full observability. Plus vDefend gives you zero-trust lateral security for every pod.
Chapter 06The Arena — Where Platforms Are Measured
The Architect pulls up the scoreboard. No hype. No marketing. Just the dimensions that matter when you’re running Kubernetes in a regulated enterprise with 500+ VMs already on VCF.
⚔️ HEAD TO HEAD ⚔️
Dimension
🛡️ Captain VKS
☁️ Cloud Twins
🎩 Red Baron
🤠 Wrangler
🥊 Bare Knuckle
Data Sovereignty
Your DC
Their DC
Your DC
Depends
Your DC
VM + K8s Unified Ops
Native
Separate
Separate
Separate
Separate
Infra-Aware Scheduling
DRS-Level
Node Groups
Topology Mgr
Manual
DIY
Cluster Scale Ceiling
500 / Supervisor
Unlimited*
Per Infra
Per Infra
Per Team
Integrated FinOps
FOCUS Native
Cost Explorer
3rd Party
3rd Party
Spreadsheet
Network Security
vDefend + NSX
VPC / SG
Built-in SDN
BYO
BYO
Licensing Model
Per-Core VCF
Per-Cluster/Hr
Per-Core Sub
Open Source
Free
Day 2 Toil
Low
Low
Medium
Medium
High
AI / GPU Conformance
CNCF AI Cert
GPU Pools
Operators
BYO
BYO
The Cloud TwinsWe still win on global reach and elastic scale.
The Red BaronAnd I still own the developer experience story. Integrated CI/CD, GitOps, developer portal — out of the box.
Captain VKS
Fair. I’m not claiming I win everywhere. But for organizations already running VCF — I’m the only Kubernetes that doesn’t create a second operational island. VMs and containers. One platform. One team. One pane.
The Architect
That’s the point everyone misses. I don’t need the “best” Kubernetes in a vacuum. I need the best Kubernetes for my stack. And my stack is VCF.
Chapter 07The Numbers Don’t Lie
💥 THE FINAL SHOWDOWN 💥
Broadcom surveyed 44 VCF 9 customers in March 2026. Here’s what they found — and why the challengers are looking over their shoulders.
51%
Less Infra Mgmt Time
46%
Less Monitoring Time
47%
Less Capacity Needed
39%
Faster MTTR/MTTI
Cluster Creep
No… NO! My sprawl… my complexity… my beautiful 37-minute deploy times… NOOOOO!
⚡ DEFEATED ⚡
The challengers watch from the sidelines. They’re not defeated — but they know the game just changed.
The Cloud TwinsWe’ll be back. Hybrid is where we’re heading too. See you at the edge…
The Red BaronImpressive numbers. But developer experience is the next battlefield. Don’t get comfortable.
The WranglerNot every ranch runs on one brand of fence. I’ll see you at the multi-cloud rodeo.
Bare KnuckleSome of us still prefer the raw fight. But… 11 minutes is hard to argue with.
The Architect
VCF 9.1 gives me 11-minute deploys, 15-minute upgrades, 500 clusters per Supervisor, intelligent DRS-based node placement, native FinOps cost tracking, self-service CaaS, open CNI choice, native Avi ingress, and zero-trust pod security. All on the same VCF stack I’m already running.
Captain VKS
And I’m CNCF Kubernetes AI Conformant. The challengers are strong — I respect each of them. But none of them can do what I do: run Kubernetes as a native citizen of your existing VMware estate.
VCF 9.1 doesn’t just iterate on VKS — it redefines the operational ceiling. Fast Deploy eliminates the provisioning tax. DRS-based placement removes manual scheduling toil. FinOps cost showback closes the last visibility gap. And with 500 clusters per Supervisor, VKS is the platform-scale Kubernetes runtime that VCF architects have been waiting for.
The challengers each bring real strengths — managed simplicity, opinionated platforms, multi-cloud freedom, zero-cost entry. This isn’t a story where the hero has no flaws. But for the Architect running a VCF estate with VMs, containers, and AI workloads under one roof — the calculus is clear.
The question is no longer “can VKS compete?” — it’s “what’s your excuse for not running it?”
This is an IT concept whereby underlying hardware and software can respond dynamically and more efficiently to changing levels of demand. Modern Cloud Infrastrastructure built on VM and Containers requires automated:
Provisioning, Orchestration, Scheduling
Service Configuration, Discovery and Registry
Network Automation, Segmentation, Traffic Shaping and Observability
What is Cloud Native Runtimes for Tanzu ?
Cloud Native Runtimes for VMware Tanzu is a Kubernetes-based platform to deploy and manage modern Serverless workloads. Cloud Native Runtimes for Tanzu is based on Knative, and runs on a single Kubernetes cluster. Cloud Native Runtime automates all the aspects of dynamic Infrastructure requirements.
Serverless ≠ FaaS
Serverless
FaaS
Multi-Threaded (Server)
Cloud Provider Specific
Cloud Provider Agnostic
Single Threaded Functions
Long lived (days)
Shortly Lived (minutes)
offer more flexibility
Managing a large number of functions can be tricky
Cloud Native Runtime Installation
Command line Tools Required For Cloud Native Runtime of Tanzu
The following command line tools are required to be downloaded and installed on a client workstation from which you will connect and manage Tanzu Kubernetes cluster and Tanzu Serverless.
Using a browser, navigate to the Kubernetes CLI Tools (available in vCenter Namespace) download URL for your environment.
Select the operating system and download the vsphere-plugin.zip file.
Extract the contents of the ZIP file to a working directory.The vsphere-plugin.zip package contains two executable files: kubectl and vSphere Plugin for kubectl.kubectl is the standard Kubernetes CLI. kubectl-vsphere is the vSphere Plugin for kubectl to help you authenticate with the Supervisor Cluster and Tanzu Kubernetes clusters using your vCenter Single Sign-On credentials.
Add the location of both executables to your system’s PATH variable.
kapp is a lightweight application-centric tool for deploying resources on Kubernetes. Being both explicit and application-centric it provides an easier way to deploy and view all resources created together regardless of what namespace they’re in. Download and Install as below:
Orchestrates image builds (delegates to tools like Docker, pack, kubectl-buildkit) and registry pushes, works with local Docker daemon and remote registries, for development and production cases
The Knative clientkn is your door to the Knative world. It allows you to create Knative resources interactively from the command line or from within scripts. Download, Rename and Install as below:
Download Cloud Native Runtimes for Tanzu (Beta)
To install Cloud Native Runtimes for Tanzu, you must first download the installation package from VMware Tanzu Network:
Navigate to the Cloud Native Runtimes for Tanzu release page.
Download the serverless.tgz archive and release.lock
Create a directory named tanzu-serverless.
Extract the contents of serverless.tgz into your tanzu-serverless directory:
#tar xvf serverless.tar.gz
Install Cloud Native Runtimes for Tanzu on Tanzu Kubernetes Grid Cluster
For this installation i am using a TKG cluster deployed on vSphere7 with Tanzu.To install Cloud Native Runtimes for Tanzu on Tanzu Kubernetes Grid: First target the cluster you want to use and verify that you are targeting the correct Kubernetes cluster by running:
#kubectl cluster-info
Run the installation script from the tanzu-serverless directory and wait for progress to get over
#./bin/install-serverless.sh
During my installation, I faced couple of issues like this..
i just rerun the installation, which automatically fixed these issues..
Verify Installation
To verify that your serving installation was successful, create an example Knative service. For information about Knative example services, see Hello World – Go in the Knative documentation. let’s deploy a sample web application using the kn cli. Run:
#kn service create hello --image gcr.io/knative-samples/helloworld-go - default
Take above external URL and either add Contour IP with host name in local hosts file or add an DNS entry and browse and if everything is done correctly your first application is running sucessfully.
You can list and describe the service by running command:
#kn service list -A
#kn service describe hello -n default
It looks like everything is up and ready as we configured it. Some other things you can do with the Knative CLI are to describe and list the routes with the app:
#kn route describe hello -n default
Create your own app
This demo used an existing Knative example, why not make our own app from an image, let do it using below yaml:
apiVersion: serving.knative.dev/v1
kind: Service
metadata:
  name: helloworld
  namespace: default
spec:
 template:
  spec:
   containers:
     - image: gcr.io/knative-samples/helloworld-go
       ports:
             - containerPort: 8080
       env:
        - name: TARGET
          value: "This is my app"
Save this to k2.yaml or something which you like, now lets deploy this new service using the kubectlapply command:
#kubectl apply -f k2.yaml
Next, we can list service and describe new deployment, as per the name provided in the YAML file:
This proves your application is running successfully, Cloud Native Runtimes for Tanzu is a great way for developers to move quickly go on serverless development with networking, autoscaling (even to zero), and revision tracking etc that allow users to see changes in apps immediately. GO ahead and try this in your Lab and once GA in production.
In the process of modernize your data center to run VMs and containers side by side, Run Kubernetes as part of vSphere with Tanzu Basic. Tanzu Basic embeds Kubernetes in to the vSphere control plane for the best administrative control and user experience. Provision clusters directly from vCenter and run containerized workloads with ease. Tanzu basic is the most affordable and has below components as part of Tanzu Basic:
To Install and configure Tanzu Basic without NSX-T, at high level there are four steps which we need to perform and I will be covering all the steps in three blog posts:
vSphere7 with a cluster with HA and DRS enabled should have been already configured
There are few topologies to setup Tanzu Basic with vSphere based networking, for this blog we will deploy the HAProxy VM with three virtual NICs, which means there will be one “Management” network , one “Workload” Network and another one will be “frontend” network which will be used by DevOps users and external services will also access HAProxy through virtual IPs on this Frontend network.
Network
Use
Management
Communicating with vCenter and HA Proxy
Workload
IP assigned to Kubernetes Nodes
Front End
DevOps uses and External Services
For This Blog, I have created three VLAN based Networks with below IP ranges:
Network
IP Range
VLAN
tkgmgmt
192.168.115/24
115
Workload
192.168.116/24
116
Frontend
192.168.117/24
117
Here is the topology diagram , HAProxy has been configured with three nics and each nic is connected to VLAN that we created above
NOTE– if you want to deep dive on this Networking refer Here , This blog post describe it very nicely and I have used the same networking schema in this Lab deployment.
Deploy VMware HA Proxy
This is not common HA Proxy, it is customized one and its Data Plane API designed to enable Kubernetes workload management with Project Pacific on vSphere 7.VMware HAProxy deployment is very simple, you can directly access/download OVA from Here and follow same procedure as you follow for any other OVA deployment on vCenter, there are few important things which I am covering below:
On Configuration screen , choose “Frontend Network” for three NIC deployment topology
Now Networking section which is heart of the solution, on this we align above created port groups to map to the Management, Workload and Frontend networks.
Management network is on VLAN 115, this is the network where the vSphere with Tanzu Supervisor control plane VMs / nodes are deployed.
Workload network is on vLAN 166, where the Tanzu Kubernetes Cluster VMs / nodes will be deployed.
Front end network which is on vLAN 117, this is where the load balancers (Supervisor API server, TKG API servers, TKG LB Services) are provisioned. Frontend network and workload network must need to route to each other for the successful wcp enablement.
Next page is most important and here we will have VMware HAProxy appliance configuration. Provide a root password and tick/untick for root login option based on your choice. The TLS fields will be automatically generated if left blank.
In the “network config” section, provide network details about the VMware HAProxy for the management network, the workload network and frontend/load balancer network. These all require static IP addresses, in the CIDR format. You will need to specify a CIDR format that matches the subnet mask of your networks.
For Management IP: 192.168.115.5/24 and GW:192.168.115.1
For Workload IP: 192.168.116.5/24 and GW:192.168.116.1
For Frontend IP: 192.168.117.5/25 and GW:192.168.117.1 . this is not optional if you had selected Frontend in “configuration” section.
In Load Balancing section, enter the Load Balancer IP ranges. these IP address will be used as Virtual IPs by the load balancer and these IP will come from Frontend network IP range.
Here I am specifying 192.168.117.32/27 , this segment will give me 30 address for VIPs for Tanzu management plane access and application exposed for external consumption.Ignore “192.168.117.30” in the image back ground.
Enter Data plane API management port. Enter: 5556 and also enter a username and password for the load balancer data plane API
Finally review the summary and click finish. this will deploy VMware HAProxy LB appliance
Once deployment completed, power on the appliance and SSH in to the VM using the management plane IP and check if all the interfaces are having correct IPs:
Also check if you can ping Front end ip ranges and other Ip ranges also. stay tuned for Part2.
Tanzu Kubernetes Grid make it very simple to upgrade Kubernetes clusters , without impacting availability of control plane and also ensures rolling update for worker nodes.we just need to run two commands to upgrade Tanzu Kubernetes Grid: “tkg upgrade management-cluster” and tkg upgrade cluster CLI commands to upgrade clusters that we deployed with Tanzu Kubernetes Grid 1.0.0. In this blog post we will upgrade Tanzu Kubernetes Grid from version 1.0.0 to 1.1.0
Pre-Requisite
In this post we are going to upgrade TKG from version 1.0.0 to version 1.1.0 and to start upgrading we need to download the new versions of “TKG” client cli , Base OS Image Template and API server load balancer.
Download and Install new version of “TKG” cli on your client VM
Download and upload For Linux – VMware Tanzu Kubernetes Grid CLI 1.1.0 Linux.
Unzip using
#gunzip tkg-linux-amd64-v1.1.0-vmware.1.gz
unzip file named will be tkg-linux-amd64-v1.1.0-vmware.1
Run #tkg version , this should show updated version of “tkg cli” client command line
Download the new version
Download OVA for Node VMs: photon-3-kube-v1.18.2-vmware.1.ova
Download OVA for LB VMs: photon-3-haproxy-v1.2.4-vmware.1.ova
Once download,Deploy these OVA using “Deploy OVF template” on vSphere
When OVA deployment completed, right click the VM and select “Template” and click on “Convert to Template”
Upgrade TKG Management Cluster
As you know management cluster is a purpose-built for operating the Tanzu platform and managing the lifecycle of Tanzu Kubernetes clusters. so we need to first upgrade Tanzu Management Cluster before we upgrade our Kubernetes clusters.This is the most seamless upgrade of Kubernetes cluster, i have ever done, so let’s get in to:
First list TKG management cluster which are running in my environment using, command will display the information of tkg management clusters
#tkg get management Cluster
Once got the name of management cluster , run below command to proceed with upgrade
Upgrade process first upgrades the Cluster API providers for vSphere, then it upgrades the K8s version in control plane and worker node of management cluster.
if everything goes fine, it should take less than 30 minutes to complete the upgrade process of management plane.
Now if you run #tkg get cluster –include-management-cluster , it should show upgraded version of management cluster.
Upgrade Tanzu Kubernetes Cluster
Now since our management plane is upgraded. lets go ahead and upgrade Tanzu Kubernetes Clusters.
Here also process is same as we did for management cluster run below command to proceed with upgrade
#tkg upgrade cluster <cluster-name>
if the cluster is not running in”default” namespace, specify “–namespace” option (when TKG is part of vSphere7 with Kubernetes)
the upgrade process will upgrade Kubernetes version across your control and worker virtual machines.
Once done , you must see successful upgrade of Kubernetes clusters.
Now login with your credential and see the Kubernetes version your cluster is running.
This completes the upgrade process, such an easy process of upgrading Kubernetes clusters without impacting availability of cluster.
Contour is an open source Kubernetes ingress controller providing the control plane for the Envoy edge and service proxy. Contour supports dynamic configuration updates and multi-team ingress delegation out of the box while maintaining a lightweight profile.In this blog post i will be deploying Ingress controller along with Load Balancer (LB was deployed in this post).you can also expose Envoy proxy as node port which will allow you to access your service on each k8s node.
What is Ingress in Kubernetes
“NodePort” and “LoadBalancer” let you expose a service by specifying that value in the service’s type. Ingress, on the other hand, is a completely independent resource to your service. You declare, create and destroy it separately to your services.
Ingress exposes HTTP and HTTPS routes from outside the cluster to services within the cluster. Traffic routing is controlled by rules defined on the Ingress resource.An Ingress may be configured to give Services externally-reachable URLs, load balance traffic, terminate SSL / TLS, and offer name based virtual hosting
Pre-requisite
Before we begin we’ll need to have a few pieces already in place:
kubectl configured with admin access to your cluster
You have downloaded and unpacked the bundle of Tanzu Kubernetes Grid extensions which can be downloaded from here
Install Contour Ingress Controller
Contour is an Ingress controller for Kubernetes that works by deploying the Envoy proxy as a reverse proxy and load balancer.To install Contour follow below steps:
Downloaded VMware Tanzu Kubernetes Grid Extensions Manifest 1.1.0 in the pre-requisite stage ,move that to your Client VM and unzip it.
You deploy Contour and Envoy directly on Tanzu Kubernetes clusters. You do not need to deploy Contour on management clusters.
Set the context of kubectl to the Tanzu Kubernetes cluster on which to deploy Contour.
This completes installation of Contour Ingress Controller on Tanzu Kubernetes Cluster.let’s deploy an application and test the functionality.
Deploy a Sample Application
Next we need to deploy at least one Ingress object before Contour can serve traffic. Note that as a security feature, Contour does not expose a port to the internet unless there’s a reason it should. A great way to test your Contour installation is to deploy the application
In this example we will deploy a simple web application and then configure load balancing for that application using the Ingress resource and will access it using load balancer IP/FQDN.This application is available within the same folder which we have downloaded from VMware inside example folder. Let’s deploy the application:
Run below command to deploy application which will create a new namespace named “test-ingress” , 2 services and one deployment.
Check the status and grub the External IP address of Contour “envoy” proxy.
Add an /etc/hosts entry to above IP addresses to foo.bar.com
Test the Application
To access the application, browse the foo and the bar services from your desktop which has access to service network.
if you browse bar, you will get bar service responding
if you browse foo, you will get foo service responding
This completes the installation and configuration of Ingress on VMware Tanzu Kubernetes Grid K8 cluster. Contour is VMware’s open source version of Ingress controller and offers rich feature to consume and can be found Here and when customer chooses to Taznu portfolio , they get Contour as supported version from VMware.
In this blog post i will be deploying Ingress controller along with Load Balancer (LB was deployed in previous post) in to tenant organization VDC kubernetes cluster which has been deployed by Cloud Director Container Service Extension.
What is Ingress in Kubernetes
“NodePort” and “LoadBalancer” let you expose a service by specifying that value in the service’s type. Ingress, on the other hand, is a completely independent resource to your service. You declare, create and destroy it separately to your services.
Ingress exposes HTTP and HTTPS routes from outside the cluster to services within the cluster. Traffic routing is controlled by rules defined on the Ingress resource.An Ingress may be configured to give Services externally-reachable URLs, load balance traffic, terminate SSL / TLS, and offer name based virtual hosting.
Pre-requisite
Before we begin we’ll need to have a few pieces already in place:
A Kubernetes cluster (See Deployment Options for provider specific details)
kubectl configured with admin access to your cluster
A Kubernetes Daemonset running Envoy on each node in the cluster listening on host ports 80/443
Now we need to retrieve the external address of the load balancer assigned to Contour by our Load Balancer that we deployed in previous port. to get the LB IP run this command:
“External IP” is of the range to IP addresses that we had given in LB config , we will NAT this IP on VDC Edge gateway to access this from outside or internet.
Deploy an Application
Next we need to deploy at least one Ingress object before Contour can serve traffic. Note that as a security feature, Contour does not expose a port to the internet unless there’s a reason it should. A great way to test your Contour installation is to deploy the
In this example we will deploy a simple web application and then configure load balancing for that application using the Ingress resource and will access it using load balancer IP/FQDN.This application is hosted at Github , can be downloaded from Here. Once downloaded:
Create the coffee and the tea deployments and services using
To access the application, browse the coffee and the tea services from your desktop which has access to service network. you will also need to add hostname/ip in to /etc/hosts file or your DNS server
To get Coffee:
If your prefer Tea:
This completes the installation and configuration of Ingress on VMware Cloud Director Container Service Extension, Contour is VMware’s open source version of Ingress controller and offers rich feature to consume and can be found Here.